Imagine six autonomous cars arriving in a new city. On the leaderboard back home, one is first, another third, another sixth. A pedestrian steps toward the lane. You might expect the ranking to predict which car yields most intelligently. This week’s most unsettling result is that it does not.
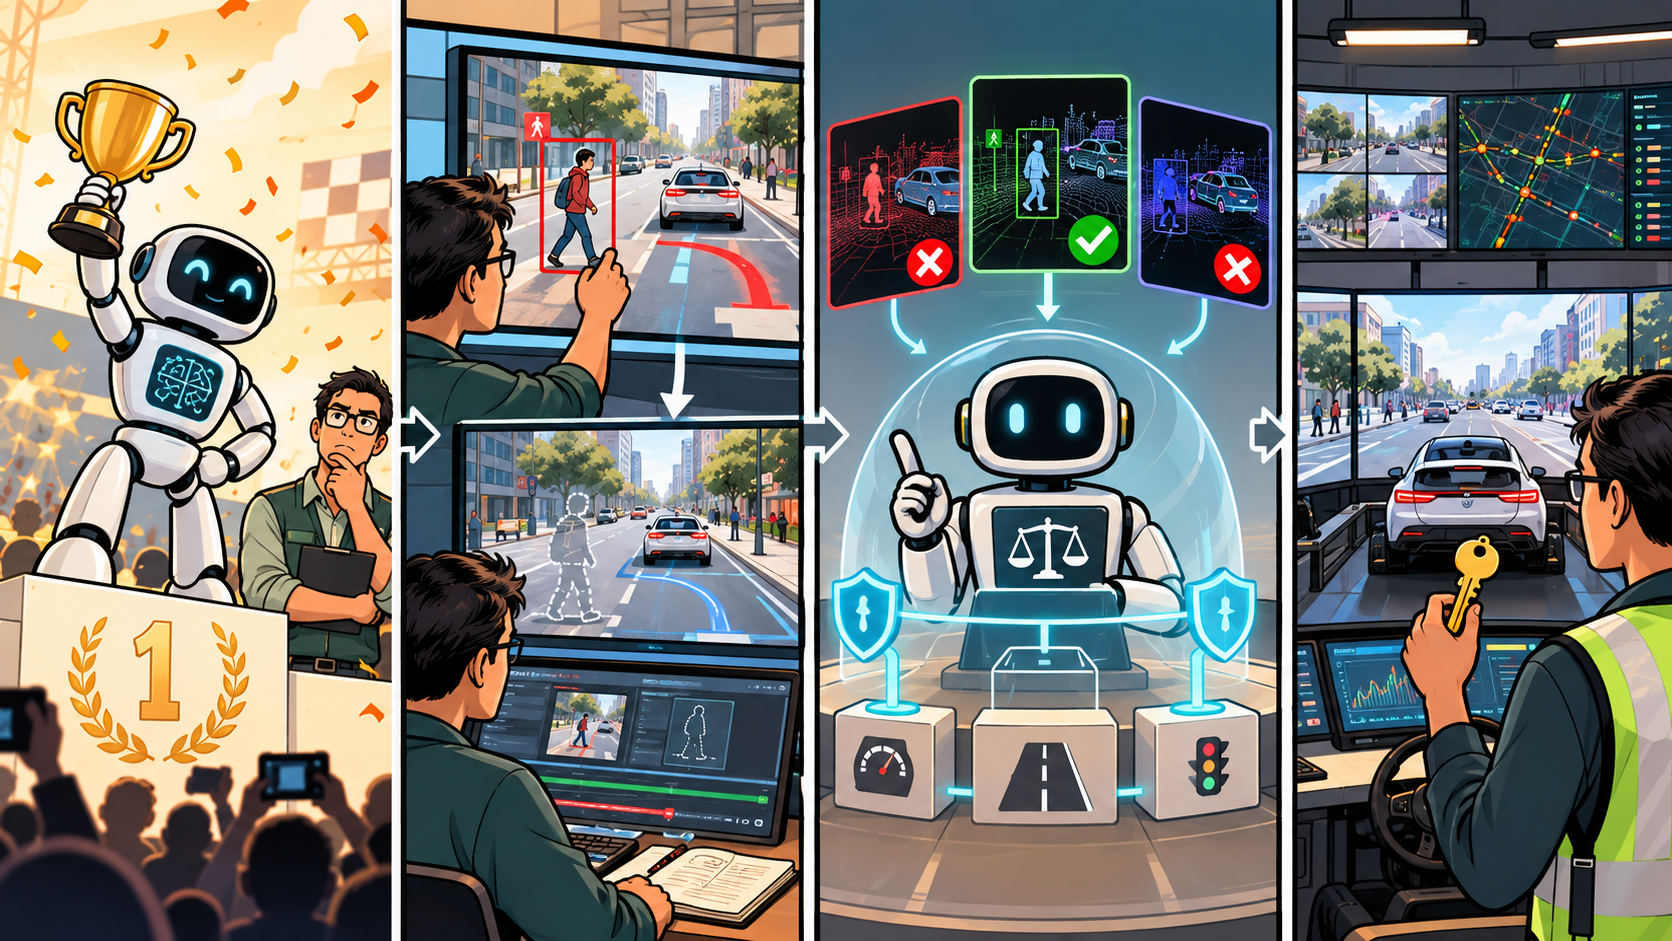
In Beyond the Leaderboard, submitted on 18 September, researchers took six released end-to-end and vision-language-action driving policies and gave them a deceptively simple examination. They selected 246 real scenes in which a pedestrian stood near the ego vehicle’s corridor, then edited every frame twice: once by removing the pedestrian and once by changing only the lighting. An independent detector checked the edits. The question was no longer “What score did the policy earn?” It was “What makes its planned trajectory move?”
Where the pedestrian lay on the planned path, only 1.9% of responses qualified as genuine avoidance. For every policy, the median pedestrian-induced clearance change was no more than 0.03 metres, and the median change in planned distance no more than 0.08 metres. Some policies looked safe because they planned timidly short trajectories—not because they recognized danger and yielded.
A scoreboard compresses behaviour into one number
The counterfactual test exposes what a ranking hides. Remove a pedestrian: does the route become more assertive? Move the same scene from daylight to artificial night without changing the hazard: does the route wobble anyway? Increase danger: does the response scale? These are behavioural fingerprints, not another aggregate score.
The counterfactual check-up
pedestrian near corridor
remove person or change light
measure what actually moved
The approach was pre-registered for transfer from left- to right-hand driving. Several relative orderings and the lighting verdict transferred; exact point values and the hazard-sensitivity verdict did not. That mixture is the point. The method can reveal which conclusions survive a new site and which were local accidents of the benchmark.
Give the model a small courtroom, not an open road
VeriFuse, also submitted on 18 September, makes the week’s architectural argument concrete. In cooperative perception, a vehicle and roadside infrastructure may disagree about a 3D object. Asking a vision-language model to invent the final geometry directly is both unreliable and expensive. VeriFuse instead creates a candidate pool from both sources and gives the frozen VLM only three legal actions: select an adequate candidate, refine an anchored proposal, or reject an unsupported infrastructure-only detection. Deterministic constraints still decide the final geometry.
On DAIR-V2X, the framework reported cooperative 3D AP50/AP70 of 0.494/0.357 and limited the relative vehicle-side bird’s-eye-view AP50 loss under 300 milliseconds of delay to 1.7%. The exact scores are dataset-specific. The more portable idea is bounded arbitration: use semantic intelligence to resolve ambiguity, while denying it the freedom to manufacture unconstrained physical coordinates.
At the traffic light, supervise the reasoning—not only the queue
ProcessLight, submitted 19 September and accepted to EMNLP 2026, attacks another form of compression. Existing LLM traffic-signal controllers often learn from the final reward: traffic improved or it did not. Valid and flawed reasoning steps are updated together. ProcessLight decomposes a signal decision into semantic steps, while its STeP-PO training method assigns credit according to both local step quality and a step’s influence on the final action.
This is promising because signal-control explanations should be inspectable before they become operational. The experiments train on synthetic flow and evaluate zero-shot on five real traffic-flow datasets inside representative simulation scenarios. That is more informative than a toy demand pattern, but it is still not live control of a junction. For this edition, ProcessLight is worth scanning closely—not evidence that an LLM belongs in a production signal cabinet.
A faster dream of the road
Diagnosis needs places where failure is cheap. ZYT-World, first posted 18 September and revised on 22 September with an updated author list, builds a streaming world model for seven-camera autonomous-driving rigs: four fisheye views and three pinhole views. A distilled one-step generator retained more than 90% of its 40-step teacher’s PSNR and SSIM and, under generator-only timing, ran 107.7 times faster. A small decoder was reported as 59.8 times faster than Wan, while 30-second rollouts and revisits tested longer-horizon consistency.
Those numbers are engineering progress, not a certificate of physical truth. The test set is internal; generator-only timing is not end-to-end system latency; and image metrics do not establish that rare hazards obey correct causal dynamics. Still, a real-time, multi-camera simulator could make counterfactual diagnosis cheaper and more repeatable—if its own errors are measured rather than hidden behind photorealism.
Two useful edge cases
JEPA Guided Diffusion separates traffic-scene understanding from video synthesis. It freezes a V-JEPA encoder and a Cosmos diffusion model, trains only a lightweight alignment module, and ranked third in AI City Challenge 2026 Track 5 with a score of 75.1297. It is worth scanning for computational modularity, although competition rank and visual prediction do not alone demonstrate decision usefulness.
X-SPUR is not an LLM-agent paper, but it is a relevant adjacent signal for connected-vehicle trustworthiness. By treating automotive-Ethernet packet fields as tokens and using causal language modelling to score per-token surprise, it achieved AUC 0.9987 on TOW-IDS, marginally above the 0.9969 reported for AERO, while eliminating handcrafted features and attributing anomalies to specific protocol fields. Its value is explainability and a second-dataset check; its limitation is benchmark evaluation rather than live adversarial operation.
Outside the lab, the same question moved into operations
The week’s deployment news echoed the papers in an unexpected way: progress was increasingly described not as “AI takes over,” but as AI operating inside a measurable boundary. On 24 September, Waymo published company-reported safety results covering more than 270 million fully autonomous miles through June 2026, including large reductions in injury-causing crashes against its human benchmarks. The numbers are consequential, but they are also a reminder that safety claims depend on methodology, comparison populations and transparent definitions—not on a single headline percentage.
Three days earlier, the U.S. FAA began limited use of SMART around Washington, D.C. The AI-supported platform centralizes 200 data streams to anticipate congestion and weather constraints, while aviation specialists remain responsible for operational recommendations. And in road mobility, Mercedes-Benz and Wayve announced a partnership to integrate Wayve’s autonomous-driving technology into future Mercedes vehicles. The research and the deployment stories therefore converged on the same engineering question: what evidence earns a model more authority?
Reading order—and the evidence boundary
- MUST READ Beyond the Leaderboard: the strongest evaluation contribution; real frames and pre-registered transfer, but open-loop diagnosis rather than closed-loop safety proof.
- MUST READ VeriFuse: a crisp design pattern for bounded semantic authority; one cooperative-perception benchmark, no public-road deployment.
- WORTH SCANNING ZYT-World: unusually concrete speed and camera-rig engineering; internal evaluation and generator-only timing require caution.
- WORTH SCANNING ProcessLight: step-level supervision is methodologically important; the reported experiments remain simulation-based rather than live-junction deployment.
- WATCHLIST JEPA Guided Diffusion and X-SPUR: useful modularity and explainability lessons, but less direct evidence for LLM-agent decision deployment.
What this changes for the systematic review
For Information Processing, VeriFuse and X-SPUR show two ways to preserve inspectability: constrain semantic arbitration and expose token-level anomaly contributions. Under Knowledge Encoding, ProcessLight turns reasoning into a semantic step tree rather than an unstructured explanation. For Component Generation, ZYT-World and JEPA Guided Diffusion generate futures that can support testing, although realism must not be confused with causal fidelity. Under Decision Facilitation, Beyond the Leaderboard supplies the week’s decisive lesson: evaluate whether an intervention changes the plan for the right reason.
The emerging gap is no longer merely “more robustness testing.” It is causal auditability under operational constraints: can a system show that a pedestrian, delay, packet anomaly or reasoning step caused the appropriate bounded response—and can it do so within the time and compute budget of transportation infrastructure?
This edition overlaps thematically with last week’s emphasis on verification placement. The material advance is sharper: last week asked where verification sits; this week supplies practical instruments for what to verify—counterfactual sensitivity, admissible action space, step-level credit and simulator throughput.
Sources & reading trail
- Beyond the Leaderboard: Counterfactual Diagnosis of End-to-End and VLA Driving Policies Under Domain Shift — 18 Sep 2026.
- VeriFuse: Bounded Vision-Language Arbitration and Reason-Guided Refinement for Cooperative 3D Perception — 18 Sep 2026.
- ZYT-World: A Real-Time Controllable World Model for Closed-Loop Autonomous-Driving Simulation — v1 18 Sep; v2 22 Sep 2026.
- ProcessLight: Process Supervision for Large Language Model Based Traffic Signal Control — 19 Sep 2026; accepted to EMNLP 2026.
- JEPA Guided Diffusion: Predictive Vision-Language Conditioning for Generative Traffic Forecasting — 18 Sep 2026.
- X-SPUR: Explainable Surprisal-Based Protocol-Aware Unsupervised Reasoning for Automotive Ethernet Intrusion Detection — 18 Sep 2026.
- Waymo — updated safety analysis across 270 million autonomous miles — 24 Sep 2026.
- FAA — SMART air-traffic management platform begins limited use — 21 Sep 2026.
- Reuters — Mercedes-Benz and Wayve partner on autonomous driving — 22 Sep 2026.
Reading note: claims and figures are presented with the scope reported by each source. Company safety analyses, preprints, simulations, competition scores and benchmark results are not treated as interchangeable forms of evidence.